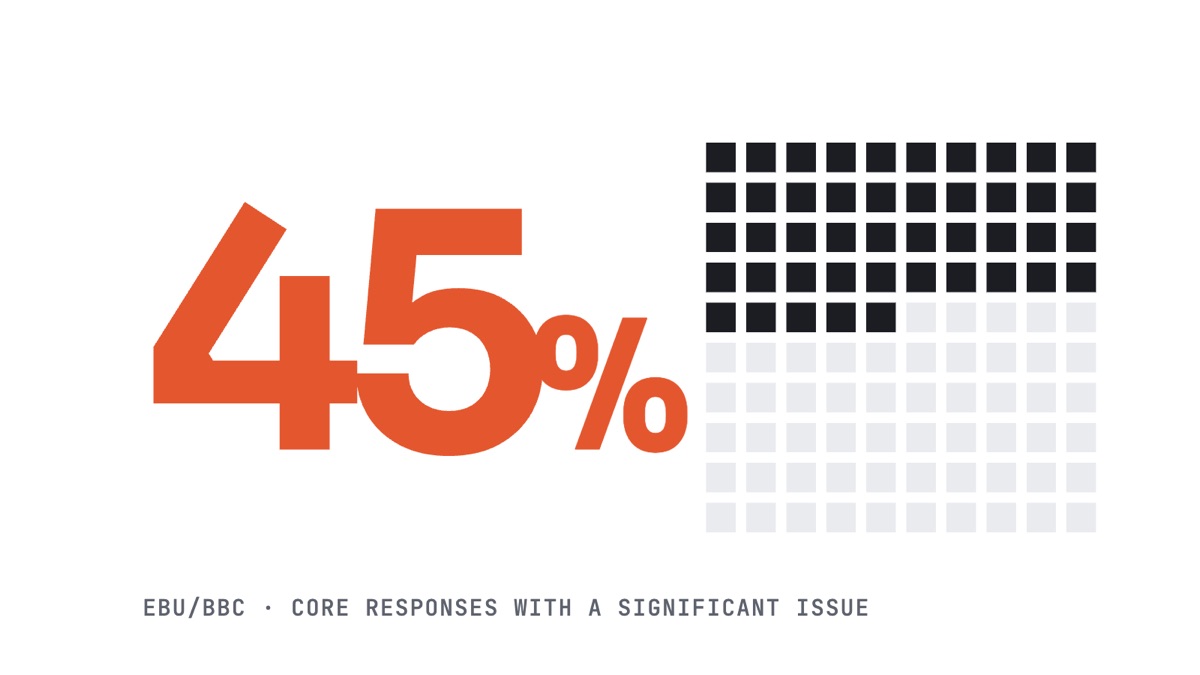
How often do AI search engines get answers and citations wrong?
From the EBU/BBC audit to the Tow Center's 1,600-query test: what the studies measured, and where their numbers stop.
Last updated
From the EBU/BBC audit to the Tow Center's 1,600-query test: what the studies measured, and where their numbers stop.
Explainers on query rewriting, fan-out, retrieval and how answers pick their citations.
GPTBot, ClaudeBot, OAI-SearchBot and friends: crawl volumes, referrals, robots.txt and blocking.
Studies and papers on answer accuracy, citation faithfulness and how LLM search behaves.
New GPT, Gemini, Claude and open-weight releases, and what each documents about search and browsing.
Research
From the EBU/BBC audit to the Tow Center's 1,600-query test: what the studies measured, and where their numbers stop.
Crawlers
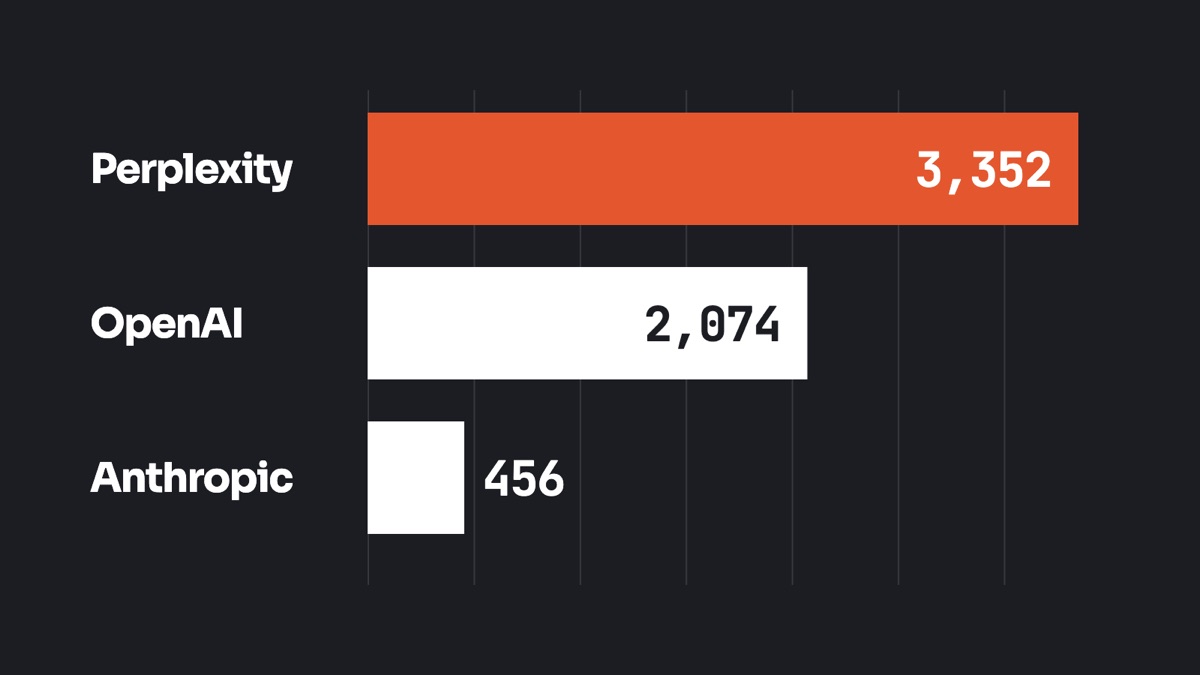
Cloudflare Radar's 17 November snapshot: 3,351.73 Perplexity crawls, 2,073.96 OpenAI crawls and 456.23 Anthropic crawls per observed referral.
Explainer
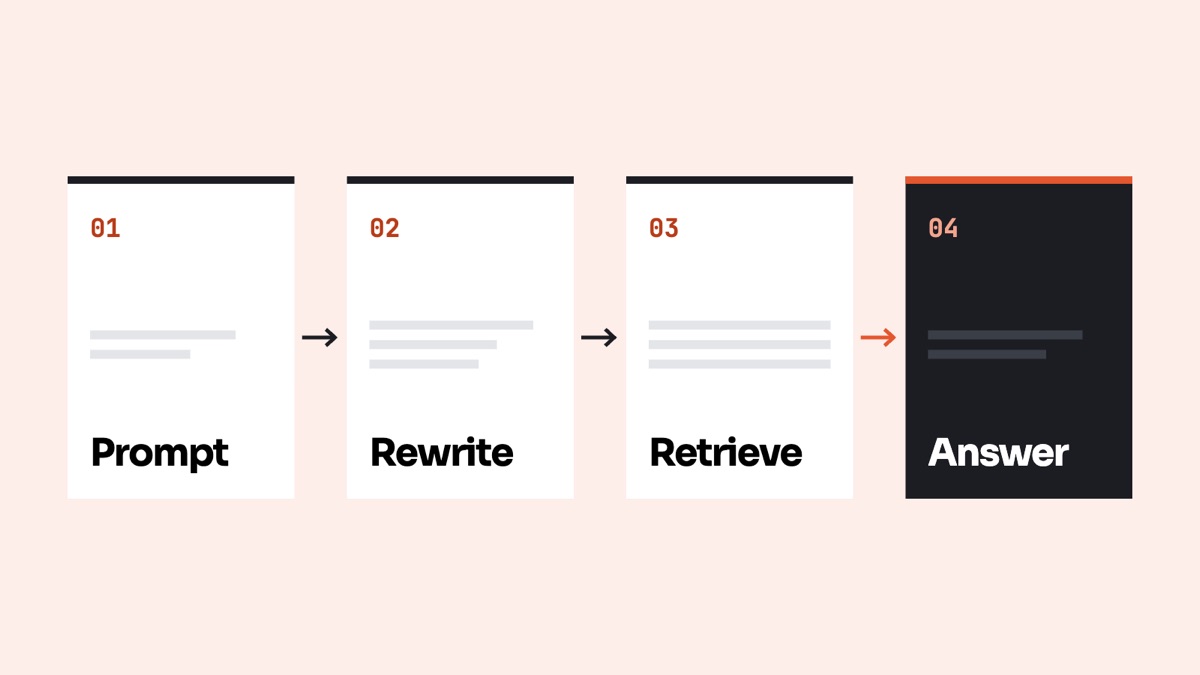
OpenAI documents query rewriting, partner search providers and OAI-SearchBot eligibility. It does not publish a ranking formula or a full provider list.
Models
Twenty-one releases between September and November. Only a few document anything new about search, grounding or browsing.
Explainer
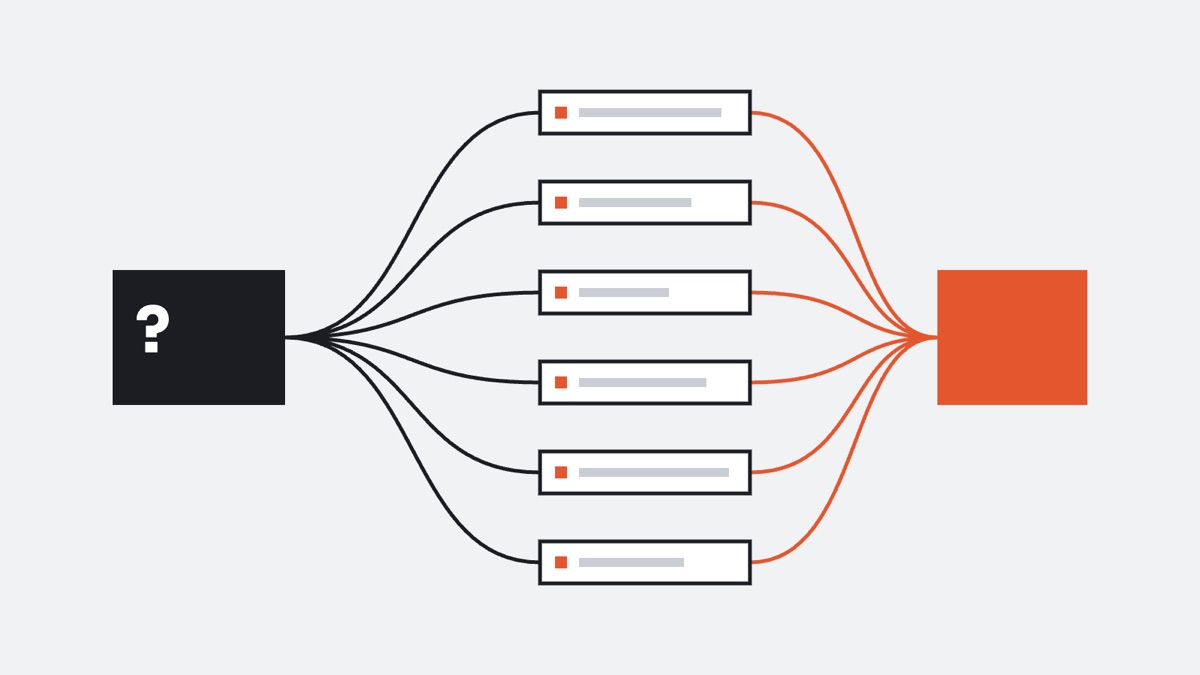
Google says AI Mode splits a question into subtopics and runs related searches at once. ChatGPT and Claude document similar, not identical, steps.
How we report
Every story is compiled from primary sources: company announcements, official documentation and published studies. Each claim carries a numbered source and a date.
Editorial standards →